> For the complete documentation index, see [llms.txt](https://docs.statuspal.io/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.statuspal.io/next/status-pages/automate-status-updates.md).
# Automate status updates
Let your monitoring tool drive your status page: point its alert webhook at StatusPal Next and have service statuses and incident notices change on their own.
If you already run Datadog, Pingdom, UptimeRobot, or any tool that can send a webhook when something goes down and comes back, you can connect it to your status page. Each automation is a webhook address tied to one service on one page. When the tool calls it, StatusPal Next reads the payload, decides whether the service is up or down, and updates the page accordingly.
{% hint style="info" %}
**Two ways to automate.** Incoming webhook automations, covered here, take alerts from tools you already run. StatusPal Next's own [monitoring checks](/next/monitoring/connect-checks-to-status-pages.md) probe your endpoints directly and can do the same job without a third-party tool. You can use both on the same page.
{% endhint %}
## Incoming webhook automations
Open your status page's **Settings → Incident Automations**. This area is admin only. Click **New Automation** and fill in:
* **Type**: the tool that will call the webhook. Pick one of the built-in providers listed in the next section, or **Custom JSONPath** for anything else.
* **Secret**: optional. A shared secret the tool includes in its requests, so nobody else can trigger the automation. The help text under the field tells you where the chosen provider sends it, for example in an `X-Secret-Token` header.
* **Service**: the component this automation controls, shown as "Service → Container" for container services.
* **Create & resolve an incident notice?**: whether a failure should open an incident notice, or only change the component's status. The difference is explained in the last section.
Click **Create Automation**. The page reloads with a unique webhook URL. Copy it into your monitoring tool as the destination for its alert webhook, and make sure the tool sends a `POST` request with a JSON body. The URL contains a token that identifies the automation, so treat it like a password. If it leaks, delete the automation and create it again to get a new one.
Each component can have one automation per type, and the Free plan allows five automations per status page. Notices created by an automation show a lightning icon that links back to it, so you can always tell an automated notice from one a person wrote. You cannot delete a service or remove it from a container while an automation points at it; delete the automation first.
## Supported provider formats
A built-in type already knows how the provider structures its alert payload and which alert means "recovered", so there is nothing to configure beyond picking it. The following providers are supported out of the box:
* Better Uptime
* Checkly
* Datadog
* New Relic
* Pingdom
* StatusCake
* UptimeRobot
* Zabbix
Pick the type, paste the webhook URL into the provider's alerting settings, and send a test alert. The help text under the **Secret** field tells you whether the provider passes the secret as a request header or a field in the body, so you know where to put it on the provider's side. If your tool is not listed, use a custom format.
## Custom JSONPath formats and secrets
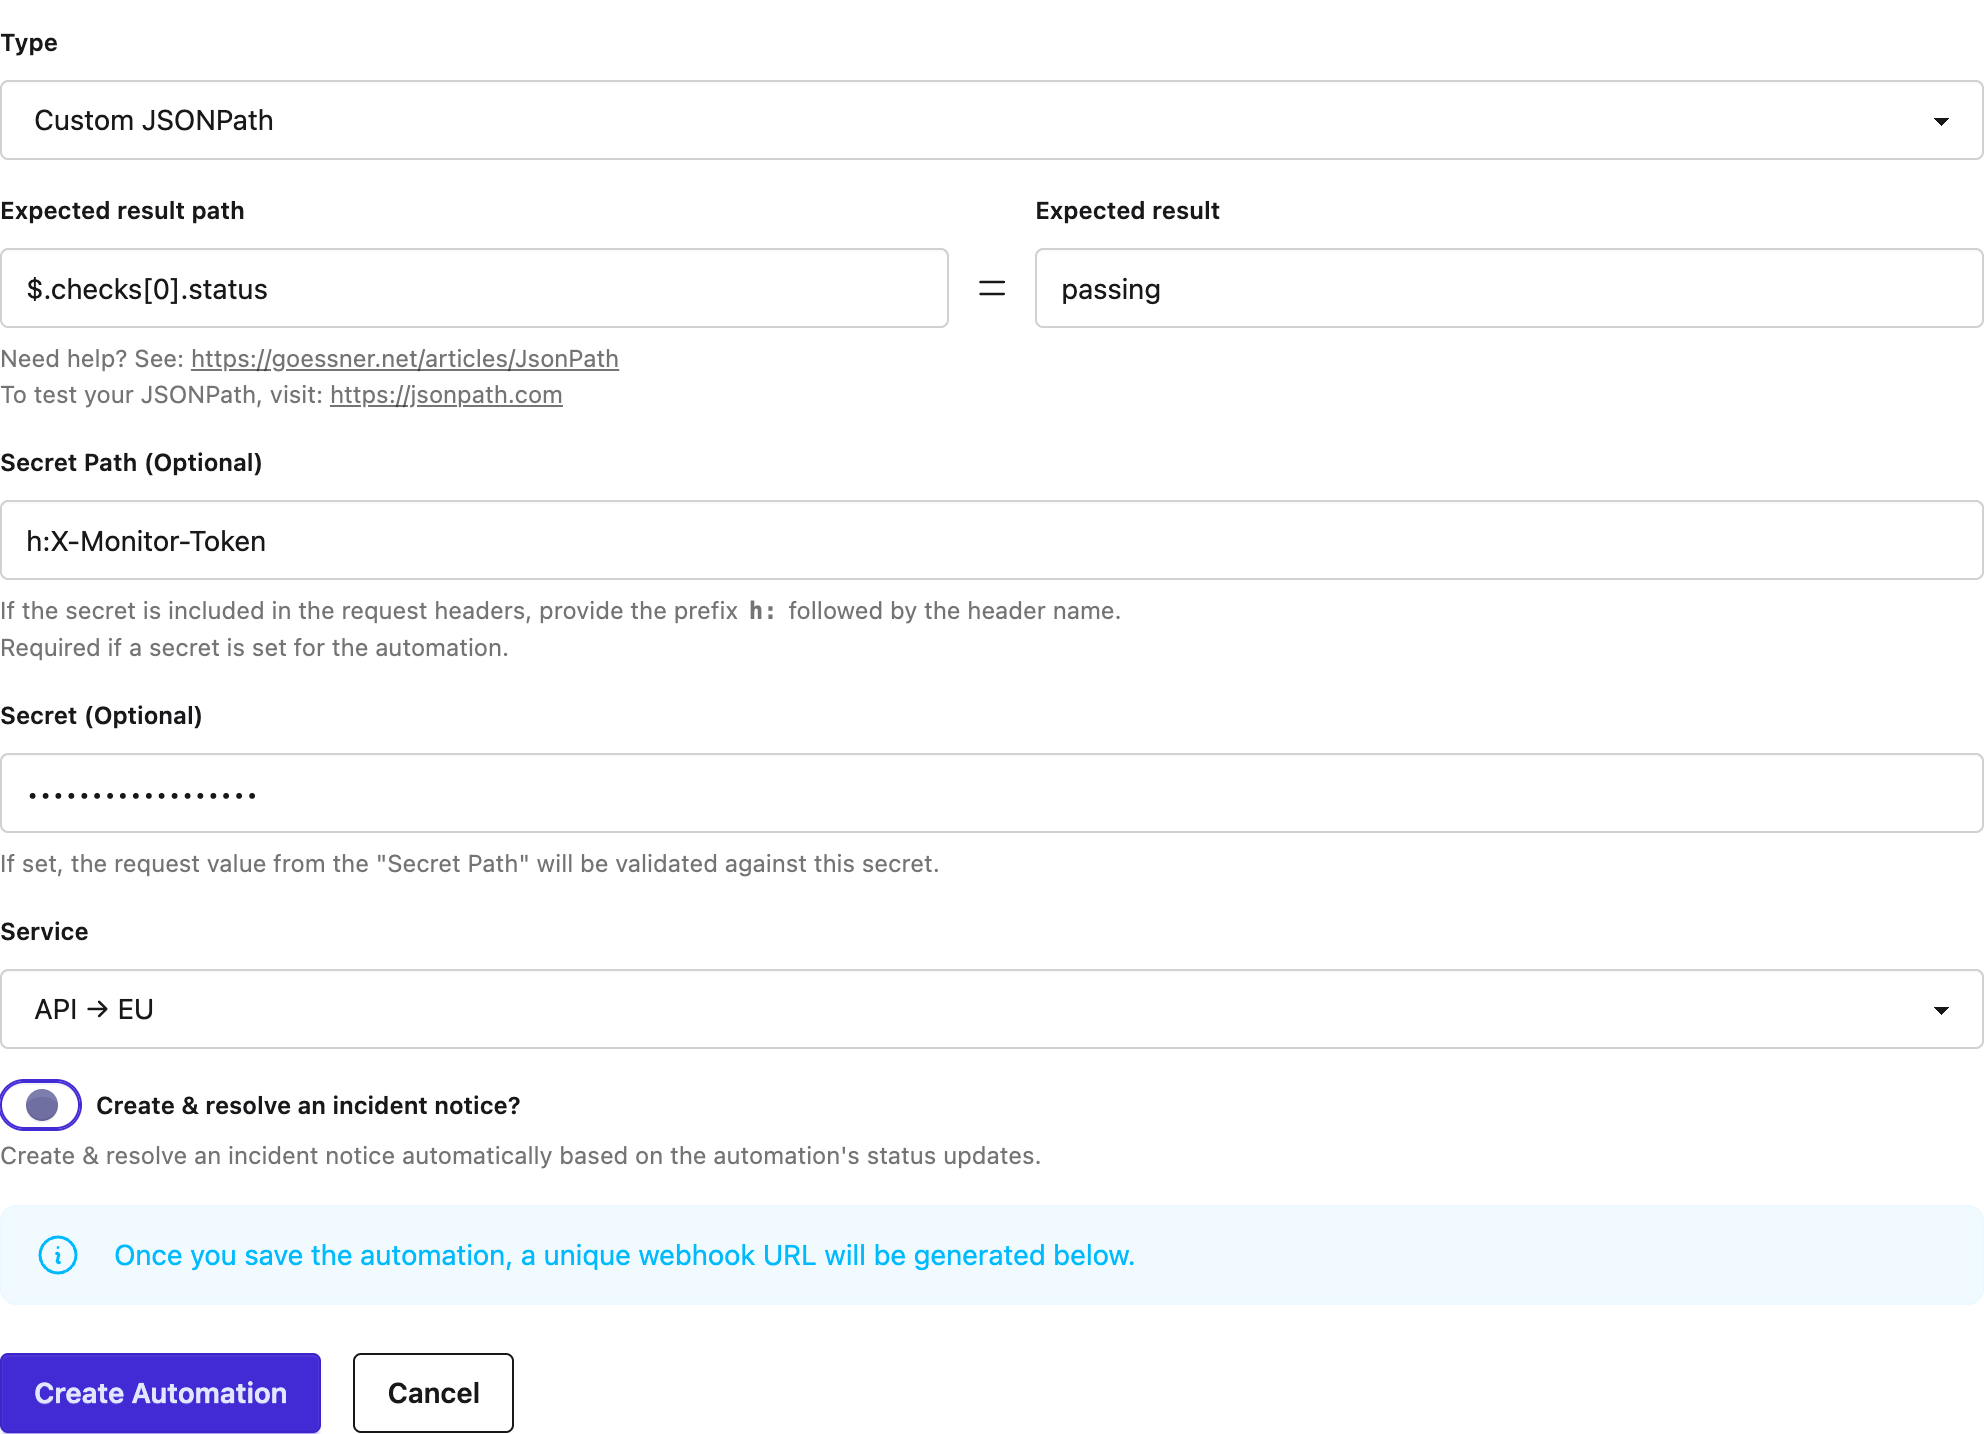
Choose **Custom JSONPath** as the type and describe the payload your tool sends:
* **Expected result path**: a JSONPath expression, starting with `$.`, that points at the field carrying the status. `$.status` reads a top-level field, `$.checks[0].status` reads into the first element of an array.
* **Expected result**: the value at that path that means the service is healthy, for example `passing` or `ok`. Any other value is treated as a failure. The comparison ignores case.
* **Secret Path**: where the secret arrives. Use a JSONPath such as `$.token` for a field in the body, or `h:` followed by a header name, such as `h:X-Monitor-Token`, for a request header. Required as soon as you fill in a secret.
* **Secret**: the value to compare against. Requests whose secret does not match are rejected with an error and change nothing.
You can edit the paths and expected value of a custom automation later. The type itself is fixed once created. Test your expression against a sample payload at [jsonpath.com](https://jsonpath.com) before saving; a path that never matches leaves the service permanently "down".
{% hint style="warning" %}
**Every call is a status decision.** The webhook does not distinguish "alert" from "heartbeat". If the payload matches the expected result the service is up, otherwise it is down. Point only alert and recovery notifications at it, not routine check results that carry other values.
{% endhint %}
## Status-only updates versus incident notices
The **Create & resolve an incident notice?** toggle decides how much an automation is allowed to do. The automations list shows it as **Reports incident notice**, Yes or No.
With it **off**, the automation only moves the component's status. A failure sets it to **Degraded**, a recovery sets it back to **Operational**. Nothing is posted and nobody is notified. The overall status banner reflects the change, and your team can still write a notice by hand if the problem is worth explaining.
With it **on**, a failure also publishes an incident notice titled **Automated Incident**, with the status **Investigating**, the component marked **Degraded**, and a first update reading "Incident created by automation." Repeated failures do not open a second notice while one is ongoing. When the recovery arrives, the notice receives a **Resolved** update reading "Incident resolved!" and the component returns to Operational. You can edit the automated notice like any other while it is open, to give it a proper title and a real explanation.
{% hint style="info" %}
**Automated notices do not notify subscribers.** The notice and its updates appear on the page and in the RSS feed, but no email or Slack message is sent. If subscribers should hear about an automated incident, open the notice and post an update with **Notify subscribers** ticked.
{% endhint %}
Choose status-only when your tool is noisy or when you want a human to decide what customers read. Switch the toggle on when the tool is reliable and a visible incident record for every outage is what you want.